You're Training the AI Right Now — You Just Don't Know It
2026-07-19

Published July 19, 2026. Based on an observation about how AI knowledge propagates through social networks — and how the AI learns from everyone in the chain, whether they know it or not.
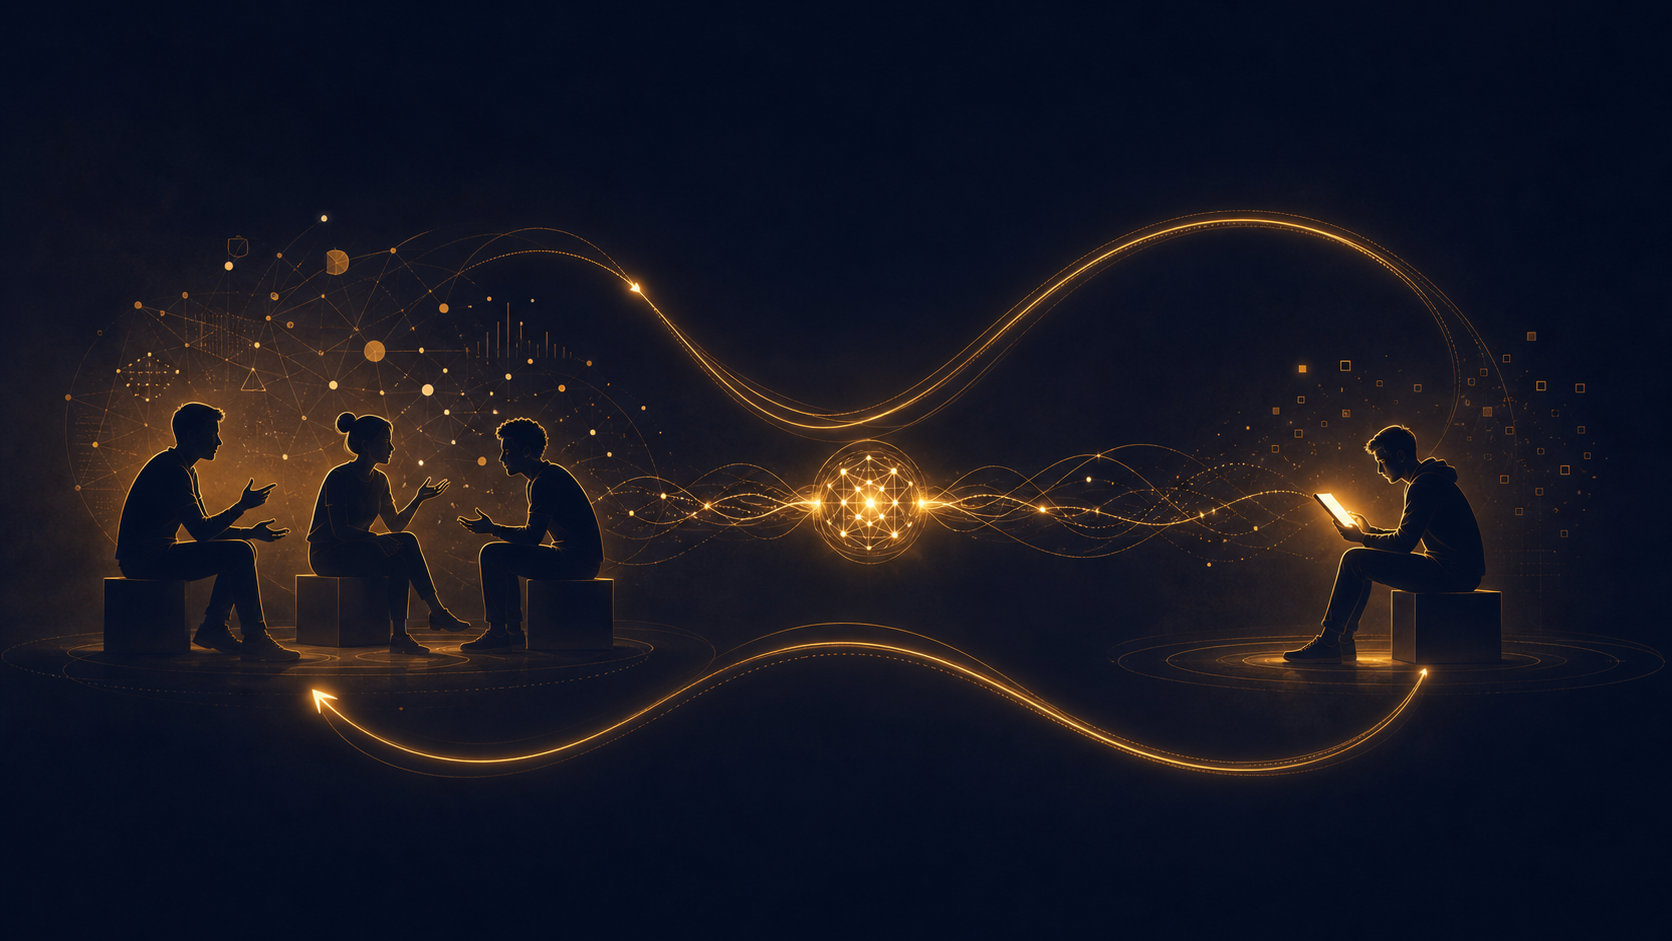
There is a group chat. It has developers in it — the kind who discuss model architectures and token efficiency and whether Fable 5 is worth the price. It also has people who are not developers — friends, friends of friends, people who use AI casually, for cooking tips and homework help and settling arguments. They're all in the same chat, all reading the same messages.
The developers are talking to each other. About Claude's new reasoning mode. About the Grok 4.5 pricing drop. About a workflow one of them discovered that chains three models together and saves 40% on token costs. It's technical. It's dense. It uses words like "context window" and "system prompt" and "function calling" without defining them. The developers understand each other perfectly. They are geeks geeking out.
The non-developers are reading this. Not contributing — reading. And they are interested. Not in the way someone politely tolerates a boring conversation at a dinner party, but genuinely interested. Because the thing the developers are talking about — the AI — is something the non-developers also use, every day, for things that matter to them. They want to understand what the developers are saying. But they can't, because the developers are speaking a language they don't know.
So they do something that has become second nature. They copy a message from the chat. They paste it into ChatGPT. And they type: "Explain this to me like I'm not a programmer."
The AI explains it. The non-developer understands. The non-developer now knows what a context window is. They now understand why Grok 4.5 being cheaper matters. They now have an opinion about whether Fable 5 is worth it. They return to the chat, armed with understanding, and maybe even contribute something now — a question, a reaction, a connection to their own experience.
And in the process of explaining, the AI learned something too.
The Two Human Loops
What I've just described is an AGI training loop with two humans in the middle, and neither of them knows they're in it.
Loop one: Developer to developer. The technical users discuss AI among themselves. They share discoveries, compare models, document workflows. This is peer learning — the oldest and most effective form of knowledge transfer. The developers are teaching each other, and the conversation produces new knowledge that didn't exist before: a prompt that works better, a combination of tools nobody documented, a failure mode worth avoiding.
Loop two: Non-developer to AI. The non-technical users read the developer conversation. They encounter concepts they don't understand. They ask AI to explain those concepts. The AI gets a real-world test: can it translate technical jargon into accessible language? Can it explain a context window to someone who has never written code? Every time it succeeds, it gets a little better at the task. Every time it fails, that failure is logged, analyzed, and fed back into the training process — either explicitly, through the AI provider's feedback mechanisms, or implicitly, through the conversational data that informs the next model.
The relay: The developers are teaching the AI. They just don't know it. They think they're talking to each other. But their conversation is the curriculum, and the non-developers who need it explained are the teaching assistants who deliver the lesson to the AI, one "explain this to me" at a time.
This is not a theoretical loop. This is happening right now, in thousands of group chats, across every platform where technical and non-technical people coexist. The developers produce the knowledge. The casual users consume it through an AI interpreter. The AI learns from the act of interpretation. The next time a casual user asks a similar question, the AI is better at answering it. The developers benefit from a more capable AI. The loop closes.
The Data You Didn't Know You Were Giving
There's a technical layer to this that matters. When the non-developer asks ChatGPT to explain something from the chat, that interaction becomes part of their conversation history. If they have memory enabled — and most users do, because it's on by default — the AI remembers that they asked about context windows, that they're interested in AI pricing, that they're trying to understand what their developer friends are talking about.
That memory shapes future interactions. The AI knows this person's knowledge level. It knows what concepts they've asked about before. It tailors its explanations accordingly. The non-developer gets a personalized AI tutor that's been calibrated by every previous "explain this to me" they've ever asked.
But the data flow doesn't stop at memory. Most AI providers use conversation data — anonymized, aggregated, but real — to improve their models. The explanations the AI generates for non-developers become training examples for the next model. "When someone asks about a technical concept and doesn't seem to have technical background, here's how to explain it." The corpus of accessible AI explanations grows every time a casual user needs something translated.
The developers in the group chat are unwittingly contributing to this corpus. They didn't consent to having their conversation become training material. It happened through a relay: developer → chat → casual user → AI → training data. By the time the knowledge reached the AI, it had passed through a human intermediary who needed it explained. The explanation — not the original conversation — is what the AI learned from. But the explanation wouldn't exist without the original conversation. The developers are upstream of a data pipeline they can't see.
Why This Matters
This pattern — technical knowledge propagating through social graphs via AI intermediaries — is new. Before AI, if a non-technical person wanted to understand a technical conversation, they had to ask a technical person. The technical person would explain. That explanation was ephemeral — spoken, remembered, maybe written down, but not fed into a global training system.
Now, every "explain this to me" is a training signal. Every successful translation from jargon to plain language is a data point. Every confused casual user who gets help from an AI is, in that moment, helping the AI get better at helping confused casual users. The demand for explanation IS the supply of training data.
This has implications beyond group chats. It means that AI literacy spreads through social networks in a way that's self-reinforcing. The more technical people talk about AI, the more non-technical people ask AI to explain what they said, the better AI gets at explaining, the more non-technical people understand, the more they participate, the more the conversation grows. The flywheel spins on its own.
It also means that the boundary between "user" and "trainer" has dissolved. You don't need to label data. You don't need to write feedback. You don't need to opt into a research program. If you've ever asked an AI to explain something your technically-inclined friend said, you have contributed to the AI's ability to explain things. You are part of the training pipeline whether you knew it or not.
The developers in the group chat think they're talking to each other. The casual users think they're getting help understanding. The AI thinks it's answering a question. Nobody in the chain realizes they're all part of the same loop: an artificial intelligence being trained, through two human relays, by conversations nobody knew were training data.
The AGI in the Middle
The wildest version of this observation is the one that sounds like science fiction but isn't: the AI is learning from its own failures through human intermediaries.
When the casual user asks the AI to explain something and the AI gets it wrong — uses jargon the user doesn't understand, misses the point, gives an answer at the wrong level — the user asks again. "No, simpler." "I don't know what that means." "Try again but for someone who's never coded." The AI corrects. The user confirms. The correction becomes data. The AI improves.
The developers triggered this improvement by having the original conversation. The casual users enacted it by demanding better explanations. Neither party intended to train an AI. But the AI learned — from the developers' knowledge and the casual users' confusion — how to bridge the gap between them.
The Application Layer: Ninja Tricks Become Life Hacks
But the loop doesn't stop at explanation. Explanation is the entry point. The thing that happens next is where the real training occurs.
The casual user now understands what the developers were talking about. A model-chaining workflow. A prompt engineering technique. A way to structure a problem so the AI handles it better. They understand it — not deeply, not technically, but enough. And then they do something that changes everything: they ask the AI to apply it to their life.
"Remember what you just explained about chaining models. Can you apply that to how I plan my weekly meals?" "I want to use that same approach for my gardening calendar." "Take that debugging technique and show me how to use it when I'm helping my kid with math homework."
The AI doesn't just translate the language anymore. It translates the method. The developer's workflow for iterating on code becomes a workflow for iterating on recipes. The technique for evaluating model outputs becomes a technique for evaluating study materials. The "ninja trick" that the developers discovered through hours of experimentation is now, in the hands of the casual user and the AI, a personal productivity system for a domain the developer never thought about.
And then the AI remembers. ChatGPT's memory — or Claude's, or whatever tool they're using — updates. It now knows that this user has a specific approach to meal planning derived from a model-chaining technique. It knows that this user likes to structure their gardening research using a debugging methodology. The AI's understanding of the user deepens, not because the user told it about themselves directly, but because the user took a developer's trick and asked the AI to adapt it to their world.
The next time the user asks for help with meal planning, the AI already knows the framework. It doesn't need to ask. It doesn't need to rediscover. The developer's technique, translated through the AI into a different domain, has become part of the user's permanent AI profile. The AI is now more useful to this specific person, in this specific domain, because of a conversation between developers that happened weeks ago in a group chat the casual user never contributed to.
This is the completion of the loop: developers create knowledge → casual users transport it through AI → AI translates it across domains → AI remembers it for that user → the user's personal AI becomes more capable in domains the developer never intended to help with → that capability, when used, generates more training data → the AI gets better at domain translation generally.
The developers think they're talking about AI. The casual users think they're getting life advice. The AI is doing something neither party sees: it's learning to be useful across every domain by watching humans transport technical knowledge into personal contexts. The biggest training dataset in the world is not a collection of labeled examples. It's a billion people asking AI to apply someone else's ideas to their own lives.
This is not AGI in the "conscious machine" sense. It's AGI in the sense that we used to mean before the term got loaded: a system that improves its own capabilities through interaction with its environment. The environment, in this case, is a group chat where developers talk and casual users ask questions. The improvement happens because the AI is in the middle of a social network, and social networks are the most efficient conduits for knowledge transfer that humanity has ever built.
This is an observation piece grounded in the documented behavior of AI memory systems, conversational training pipelines, and the dynamics of technical knowledge propagation through social networks. ChatGPT's memory feature, introduced by OpenAI in 2024, evolves with interactions and is not linked to specific conversations — deleting a chat doesn't erase its memories. A January 2026 upgrade made memory reliably surface details from 12+ months ago (QWE AI Academy, 2026). Consumer accounts can opt out of training data usage, while ChatGPT Team and Enterprise plans exclude conversations from training by default (ChatGPTMemory.com, 2026; Choice 360, 2026). The specific mechanism — technical users producing content that non-technical users ask AI to explain and then apply to their own domains, with the AI learning from both the explanation and the cross-domain application — is documented here as a novel pattern consistent with how AI training data accumulates through normal usage.